


docs/user/deploy/deployments.md
title: Deployments description: Stage changes, deploy them, follow each deployment, and know what happens when one fails.
Nothing you change in the dashboard reaches your servers until you deploy it. Your edits pile up as staged changes, like a draft, and Deploy makes your servers match. Each deploy becomes a deployment, with its own page and logs.
Stage changes
Settings save as you change them. Config files save when you click Save. Your services keep running as they were. A staged field turns pink until you deploy it (hover it to see what's running now), and the bottom bar counts your changes, like 3 changes.
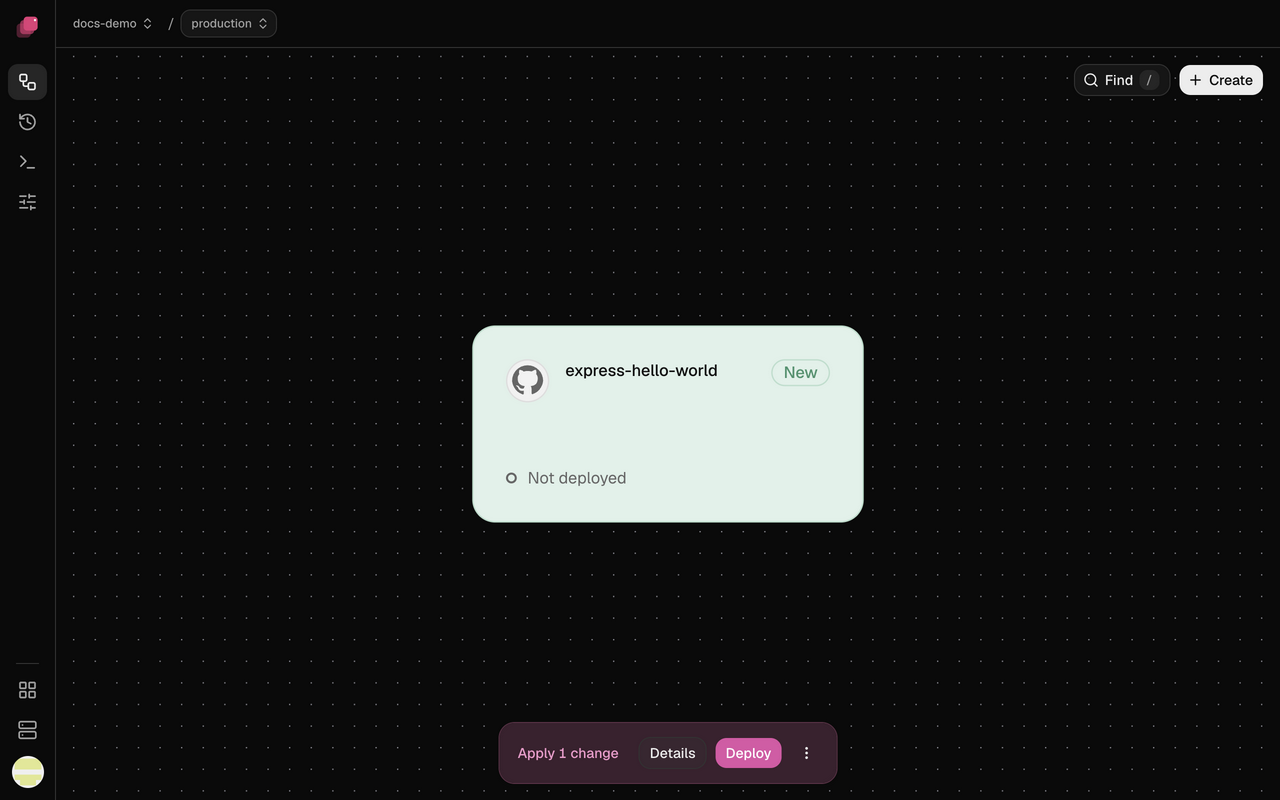
Deleting a service, volume, variable or domain is staged too; discard it and it comes back.
A few settings apply the moment you change them instead, and Discard doesn't undo them: Auto-deploy, Wait for CI, Watch paths, Preferred Builder and a new secret for a private image.
Deploy your changes
- In the bottom bar, click Details to review each change. Add a Message (optional) if you like.
- Click Deploy changes. Deploy in the bottom bar skips the review.
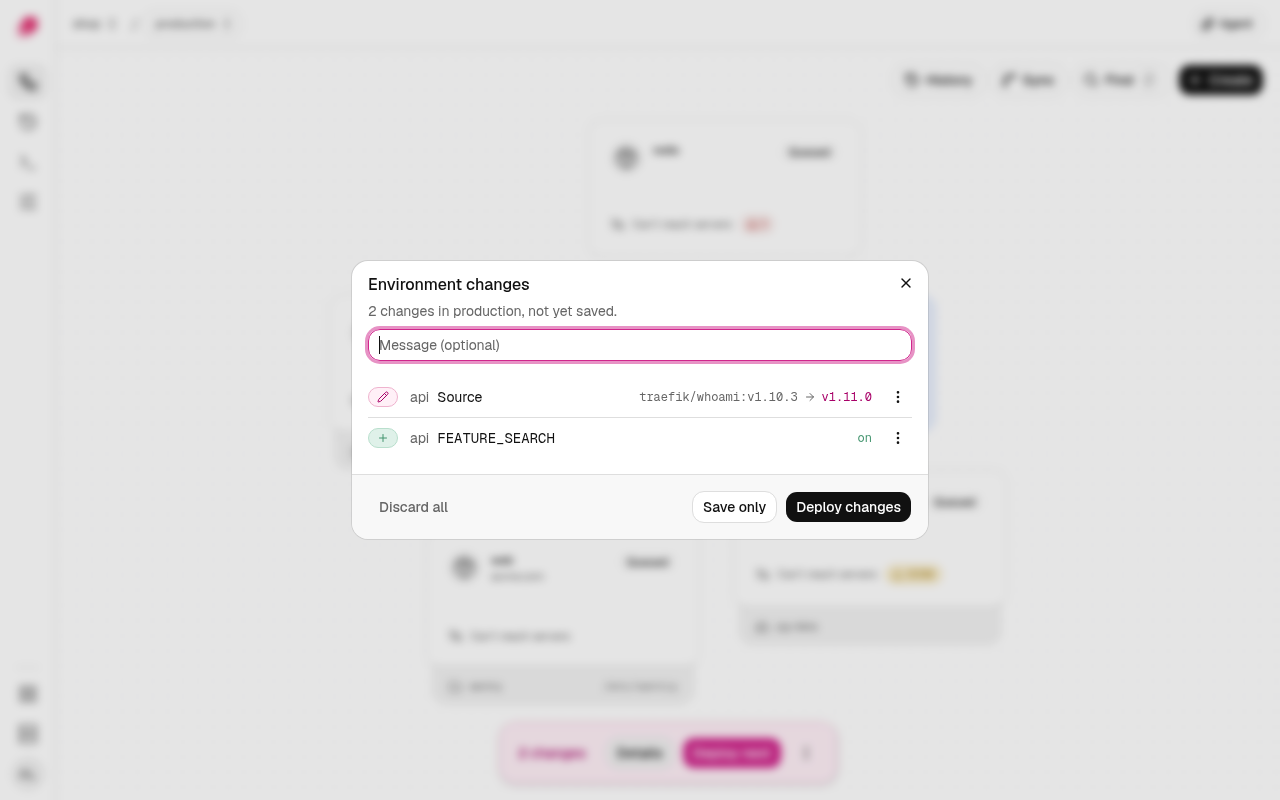
Ployz opens the new deployment's page. A deploy covers the whole environment, not only what you
changed: every GitHub service moves to the newest commit on its Git branch, and if you've added
or lost a server, replicas spread over the servers you have now (if a service's volume was on a
lost server, see When a server goes down).
Everything else keeps running as it is. A secret that is Not set never stops a deploy: the
deploy skips it, and any variable that references it, and warns. A
broken reference, to a service or
variable that isn't there, doesn't either: the deploy leaves that variable out the same way, or
leaves the reference empty in a config file, along with any reference that reads it, and the
deployment's page and ployz deploy name each one.
Save only in Details, in the bottom bar's ⋮ menu, or on Deploy while you hold Alt,
records your changes and optional message without deploying them. Ployz shows Saved, not
deployed. Your
next deploy takes them along, including one started by a push to GitHub; unsaved changes stay
behind. Saving again with no changes creates no new version. The CLI calls this
ployz deploy --skip-deploy, and accepts --message.
To undo, click Discard beside a change, or open ⋮ and choose Discard all changes.
Discard all changes returns everything to your latest saved version, including a staged
rollback. Discarding a service or volume you never deployed deletes it. Discard does not save a
version. When your latest saved version is not running, for example because its deploy failed,
the bottom bar shows #4 not running with Deploy instead of a change count. Neither its ⋮
menu nor Details offers Discard all then, since nothing is left to discard.
If you discard saved changes back to what is deployed, Details still shows the draft reversal.
Saving records that reversal; Discard on its row returns it to the latest saved value.
In the CLI, ployz discard with no path drops every staged change in the environment, including
changes someone else staged from the dashboard or an agent, and lists each one it dropped. Pass a
path, such as ployz discard web.env.KEY, to drop only that change. It also names each saved change
it took out and the command that brings it back, such as ployz discard web. ployz diff lists
those rows and ployz status counts them. Plain ployz discard returns each service to what is
deployed, or, for a service a queued or running deploy is changing, to the value that deploy is
bringing in. ployz discard --target review matches the dashboard's Discard all changes and
goes back to your latest saved version.
The dashboard's Deploy needs a staged change. To ship the same commit and settings again, click Redeploy on the newest deployment. To move GitHub services to their branch's latest commit with nothing staged, use the CLI:
| 1 | ployz deploy |
Saved history
Open Deployments in the sidebar, then Versions, to see this environment's saved versions. Each version is titled from what it changed unless it was saved with a message, and lists its changes one per row, folding past three. The first version lists what it created. Live marks the version the latest fully applied deployment shipped. Failed marks the newest version when its latest deployment failed; a later deployment of it clears it. A version saved but not deployed yet has no badge. The version's ⋮ menu:
- Undo these N changes reverses that version's changed fields and keeps the versions saved after it. The first recorded version has no earlier version to undo.
- Roll back to #N stages that version's complete configuration, undoing every later version. The newest version has nothing to roll back to. After a failed deploy, rolling back to the Live version deploys too: Deploy saves it, and services that already match are left running. Like every deploy, it moves GitHub services to the newest commit on their branch, so a branch that moved on since ships its newer code.
Each row's ⋮ undoes that one change. A change the same save tied to others undoes with them, and the menu says how many: adding a Service together with another Service's reference to it, a Volume together with its mounts, or a Source with its repository and branch. Every action stages on the canvas; nothing is saved or deployed until you do.
If an action would overwrite draft changes, the confirmation lists exactly which fields. Cancel changes nothing. If someone edits the environment after your review, reopen the action to review the new draft. Save or Deploy makes the staged result a saved version.
Undo and Roll back pass the same checks as an edit made by hand. One that would reuse a name or hostname another Service took since, or break a rule, is refused with the reason, and nothing is staged. One that leaves a reference to a deleted Service stages, and shows it as a Broken reference.
History restores configuration references. It never brings back a sealed value. A sealed variable that still exists keeps its current value, and one added since stays. A sealed variable deleted since, or one inside a Service that comes back, comes back Sealed and Not set. A toast names those variables, the Service shows · N not set, and its Variables tab offers Set value on each. Deploys leave a Not set variable out of the container until you set it. A variable that was ever sealed can't come back as plain text. A version that only set sealed values has nothing to undo, so its Undo is disabled and says Sealed. Nothing to undo. History does not recover deleted Volume data or undo private-image credential rotations. An accepted deployment and its redeploys keep their original snapshot while you edit the draft.
From the CLI, ployz history lists versions with when and by whom each was saved, the settings
it changed and its message; the live one says (live). ployz history restore 2 --preview
reviews a rollback without writing. ployz history undo 2 stages an Undo. One that would overwrite
draft changes refuses, names those fields and gives the same command with --accept-overwrite;
run it only after reviewing them. Both list each variable that came back Not set, and
--json carries them as not_set. The agent's history tool does the same by revision
number; one that would overwrite draft changes refuses and names them first.
When another deployment is running
An environment runs one deployment at a time. While one runs, Deploy reads Deploy next and yours waits as Queued. If you deploy again while one is waiting, the newest one takes its place.
On the canvas, Deploying shows only on the services the running deployment restarts. A service it leaves running keeps its staged changes on its card.
Follow a deployment
While a deployment runs, the bottom bar shows it. Once it ends, the bar shows Deployed for a few seconds, or Failed until you dismiss it, with Logs to open its page. Failed stays after a reload and in other tabs, as long as the failed deployment is the newest one.
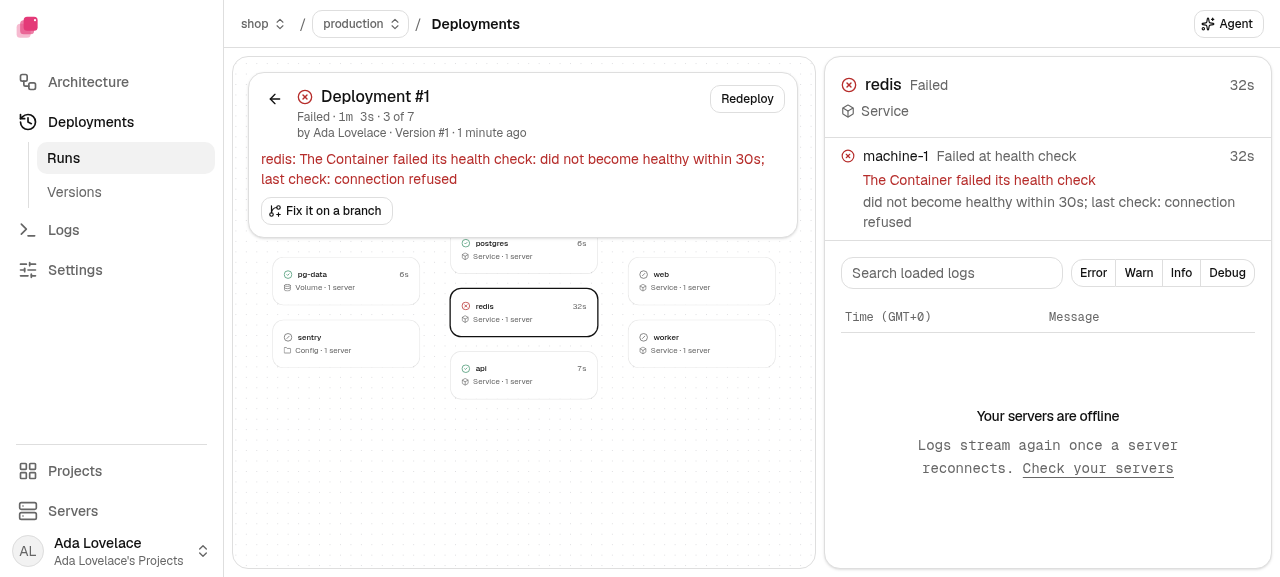
Runs, under Deployments in the sidebar, lists every deployment, newest first. A deployment's page shows its status, who started it and, if it failed, the reason in red under the header. Below that is one card for each build, service, volume and config it touched, laid out left to right in the order they deploy. Click a card to see each server's progress and its logs. A build's card shows the build output, and a service's card shows what its new containers printed. A failed deployment opens on the card that failed.
| Status | What it means |
|---|---|
| Queued | Waiting for another deployment, or for GitHub Actions to build it |
| Deploying | Building, then rolling out |
| Deployed | Every change applied |
| Failed | Something stopped it. A service marked Not attempted never started. |
| Cancelled | Someone cancelled it |
| Unknown | Ployz can't tell what applied. Redeploy it. |
From the CLI, ployz deployment ls lists the environment's deployments, newest first, with
each one's status and saved revision. To inspect per-server progress, run:
| 1 | ployz --json deployment show 37 |
Each service's nodes[].rows[] records the servers where work ran, its state, and its start
and finish times. Each row identifies its server with machine_id. The server field is a
display name and can repeat across servers. Volume rows use the same Machine IDs to group
the work of services that mount them. A running row also names its phase. Failed rows retain
the cause chain and up to ten final container log lines when available, with sealed variables
and secret-shaped values such as password=… replaced. Other values, such as NODE_ENV from
the image, show as the container printed them. These outcomes stay with that deployment
when you deploy again. Unchanged services have no rows because no server work ran.
If the runner stops reporting, unfinished rows read unknown. Completed and failed rows keep
their recorded outcomes.
Redeploy or cancel a deployment
- Redeploy, on any finished deployment, ships that deployment's commit and settings again. Your staged changes, volume changes included, wait for your next deploy, and Copies wait for Deploy beside the button says so when volume changes are staged. To ship a fix, change it and deploy instead. A deployment whose restore failed can't be redeployed, because it would mount the new volume empty. Redeploy refuses with "Restore failed. Restore again."
- Roll back by clicking Redeploy on a deployment older than one that ran, even one that
failed partway. Ployz asks first, in Roll back to #4, and names what it undoes, such as
Undoes #5 and #6. The rollback ships #4's commit and settings. Services added after #4 stop,
and they and the other settings saved after #4 show as staged changes again. A volume #4 deleted
that a later deployment brought back is deleted again only after you accept it. In Deletes
data, type the project and environment, such as
shop/production. The CLI refuses and prints the command that accepts it with--accept-volume-loss. If another deployment runs while you confirm, Ployz asks again with the new list. While a newer deployment is running, Redeploy on an older one refuses with "Wait for #5 to finish, then redeploy." A queued one gives way, as when you deploy again, and so does one whose runner stopped reporting. - An applied removal or shutdown can't be redeployed: there is nothing left to ship. One that
failed, was cancelled or reads
unknowncan. - A rollback lasts until your next push or deploy, which ships your saved settings again. A deploy ships your latest commit too; a push, only to the services it builds. To keep the rollback, revert the commit in Git and change the settings back.
- Cancel, on a running deployment, stops it at its next step. What it already changed stays until your next deploy.
- On a queued deployment, Deploy now starts it if nothing is running ahead of it, and ⋮ → Cancel deployment… takes it out of the queue.
The CLI does the same with ployz deployment redeploy, start and cancel. Before a rollback,
ployz deployment redeploy 4 asks in a terminal; outside one, or with --json, it needs --yes.
A rollback that deletes volume data also needs --accept-volume-loss <volume> and the
--expect-version it prints.
The agent can too, and its redeploys wait for you to approve.
Deploy without downtime
Ployz starts the new replicas of a service alongside the old ones and waits until they're all ready. Then every server switches the service's traffic to the new replicas at once, and the old replicas stop once every server has switched, so your app keeps serving. A server that stops answering holds the old replicas for at most five minutes; after that they stop anyway. Before any replica stops, its server marks it as stopping so every server taking web traffic stops sending it requests, and the replica stops a few seconds later.
- Set a health check. Under Settings → Deploy, set Healthcheck to an HTTP path like
/upor a command likepg_isready -h 127.0.0.1. A new replica is ready when the path answers with a 2xx status or the command exits 0. A redirect, tohttps://or/loginfor example, fails the check. Without a health check, the old replica stops a few seconds after the new one starts, ready or not. The databases Ployz creates come with one. - A service with a volume has a short gap. Its old replica stops first, so two never write the same files. To change that, see Choose how a deploy replaces replicas.
- Migrations run first. A Pre-deploy command, like
npm run migrate, runs once with the new code before any replica is replaced. If it fails or runs past 5 minutes, the deployment fails and the old version keeps running. - Services that depend on each other start in order. If
web's variables reference${{ postgres.DATABASE_URL }},postgresswitches first, and passes its health check first if it has one. Services that don't depend on each other deploy at the same time.
Choose how a deploy replaces replicas
Under Settings → Deploy, Update order picks how a deploy swaps old replicas for new ones. Whichever you choose, visitors reach the new version only once every new replica is ready.
| Update order | What happens | Downtime |
|---|---|---|
| Start first | New replicas start beside the old ones, and the old ones stop once the new ones are ready. Two copies run for a moment. | None |
| Stop first | On every server at once, each old replica stops, then its replacement starts. Traffic moves to the new replicas when they're all ready. | From the stop until every new replica is ready |
| Rolling | Stop first, one server at a time. The old replicas on the other servers keep serving until the last server's turn. If a server's new replica fails, the servers after it keep the old version. | From the last server's stop until every new replica is ready |
| Automatic | Stop first for a service with a volume, Start first for the rest. | As above |
Automatic is the default. A service with a volume can use Start first only when the volume allows shared writes, because both copies write to it at once. Otherwise Ployz refuses the change and says to choose Stop first or allow shared writes.
If a new replica fails, Ployz starts the old replicas it stopped again, whichever order you chose.
When a deploy fails
Where a new replica doesn't come up, the old ones keep serving. Ployz doesn't roll back: a service that already switched keeps the new version, services that depend on the failed one stay as they were, and services that don't depend on it may have switched already.
Warning
Ployz doesn't undo a pre-deploy command. If a migration ran and the deploy then failed, your database keeps the change while the old version of your app runs against it.
A failed deploy drops the volume change it failed on. Volume changes it never got to go back to your staged changes, and Details marks them Not reached. Deploy again to run them. What the dropped change leaves behind depends on how far it got:
- A move that failed before the handover leaves the volume on its old server, with all its data. Stage the move again when you're ready.
- A move that failed after the handover is not undone: the volume belongs to the new server, and your service stays down until the move finishes there. The move stays in your changes, so deploy again to finish it. See When a move stops.
- A restore that failed is taken back. Your services mount the old volume again, and the new volume goes away. If Ployz can't take it back when the deploy fails, your next deploy fails with "Restore failed. Restore again." and takes it back then. Restore again once you fix the cause. Redeploying that deployment is refused.
- A deploy that shipped a restore it couldn't claim fails before it copies anything, with "the restore waits for the next Deploy." The restore stays staged, so deploy again.
Fix the cause and deploy again; see Troubleshooting deployments. Or click Fix it on a branch on the deployment's page to try the fix in a branch first.
Confirm a deploy that deletes data
When a deploy would delete a volume's data, like a deleted volume or database, a removed mirror or
an old copy a move replaces, Deletes data lists what goes. When it makes a mirror the primary
because the primary's server isn't answering, the title reads Data loss, since the writes after
the mirror's last refresh are lost. Type your project/environment, like my-app/production, and
click Deploy. If you didn't mean it, cancel, then discard the change in Details.
Save only asks the same way, under Next deploy deletes data. Saving deletes nothing and starts no deploy. Your confirmation is saved with the change, so the next deploy deletes that data without asking again. That holds for a deploy you start and for one a Git push starts.
Ployz asks again only when what it would delete changed since you confirmed. That happens when another server starts holding that data, or someone stages a different copy change on that volume. A Git push can't ask, so it keeps the data instead, and so does a push when Ployz can't reach your servers to check. Your next deploy then asks.
From the CLI, ployz deploy and ployz deploy --skip-deploy stop and print the command to run
instead. It names each volume that loses data, like
ployz deploy --skip-deploy --accept-volume-loss postgres-data --expect-version …. Run it only if
you mean it.
If Ployz can't check your servers for that data, the deploy refuses and deletes nothing. It names
the server it couldn't reach, or the server that answered with an error, and shows that error on the
cause: line. When you passed --connect and Ployz doesn't know which server that is, it names the
address you gave instead. With --json, the error's cause lists it. Try again once that server is back or
the error is fixed.